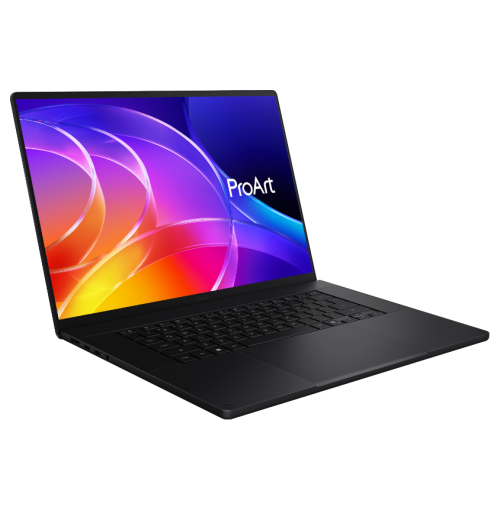
ASUS ProArt P16 64GB
- NVIDIA RTX Spark N1X 20核心 Arm CPU
- Blackwell RTX 6144 CUDA GPU
- 64GB LPDDR5X 統一記憶體
- 1TB NVMe SSD 儲存(可升級 2TB/4TB)
- 16吋 4K OLED 120Hz 觸控螢幕
- Windows 11 Pro(Arm 版)、1.77kg
- 3年保固,10月下依序出貨
NVIDIA RTX Spark N1X 整合 20 核心 Grace Arm CPU 與 Blackwell RTX GPU,最高搭配 128GB 統一記憶體,可在筆電上執行大型語言模型與 AI 開發工具。MAQ 現正接受 ASUS ProArt P16、MSI Prestige N16 Flip AI+、Microsoft Surface Laptop Ultra 三款、各 64GB 與 128GB 版本預訂:ASUS 10 月下旬依訂購順序出貨、MSI 預計 11 月中、Surface 預計 11 月上旬;ASUS 與 MSI 可加購升級 SSD。
三款規格與 MacBook Pro 比較 規格比較
Build your own AI workstation with ease. On the MAQ website, configure top-tier hardware yourself, with fully transparent pricing. From the processor and memory to the latest NVIDIA / AMD AI GPUs, everything is customized to your needs. Even better, machines come with ComfyUI, Stable Diffusion, and various large language model (LLM) AI Python development environments preinstalled — plug in your new computer and start creating or researching right away.
Configure Your Workstation Configure a PC
After-sales support means one less thing to worry about. If any system issue comes up, our expert team provides remote assistance to resolve it quickly. If your computer needs repair or an upgrade, we can also provide a loaner unit so your work continues without interruption (available to contracted customers). From pre-sale configuration advice to after-sales use and support, we're with you every step of the way, so you can focus on what matters most without worrying about the technical details.
Configure Your Workstation Configure a PC
Depending on spec, it can run local inference for gpt-oss-20b/120b, Llama 3.3 70B, Qwen3 32B at 4-bit, Gemma 4, and more. The RTX PRO 6000 96GB model can load a quantized 120B model; the 32GB-class models (AI-Medium's Radeon AI PRO R9700, AI-Medium-Gemma's RTX PRO 4500) run 20B-class quantized inference or 13B full-precision inference smoothly.
We recommend at least 48GB of GPU VRAM (such as an RTX PRO 5000, or multiple GPUs pooled together), 64GB+ of system RAM, and an NVMe SSD to speed up weight loading. MAQ's AI-High uses an RTX PRO 5000 48GB card, which sits right at this entry spec; for more headroom, see the AI-Highend with an RTX PRO 6000 96GB card.
Machines ship with Ollama, PyTorch, CUDA, vLLM, ComfyUI, and other inference/training frameworks preinstalled, along with agentic AI development tools such as Claude Code, Cursor, Codex CLI, LangGraph, and CrewAI. Depending on the model, matching LLM weight files (such as gpt-oss, Llama, or Gemma) are also preloaded — the machine is ready to use out of the box.
MAQ provides remote technical support, help with the software environment, and a loaner service for contracted customers (a comparable-spec loaner during repairs) to help resolve system issues without interrupting your work. Contracted customers are covered by next-business-day on-site service anywhere in Taiwan.
If you mainly work in macOS with the MLX framework, or edit 4K/8K video, a Mac Studio's high unified memory (up to 512GB) and low power draw are a good fit. If you need the CUDA ecosystem (PyTorch training, ComfyUI, vLLM), an RTX workstation is the better choice.
Yes. MAQ uses standard ATX cases and industrial-grade power supplies, so the GPU, memory, and SSD can all be upgraded later — by you or through us — avoiding the lock-in of an all-in-one machine.